Understanding CAP through the decisions engineers make when systems lose contact.
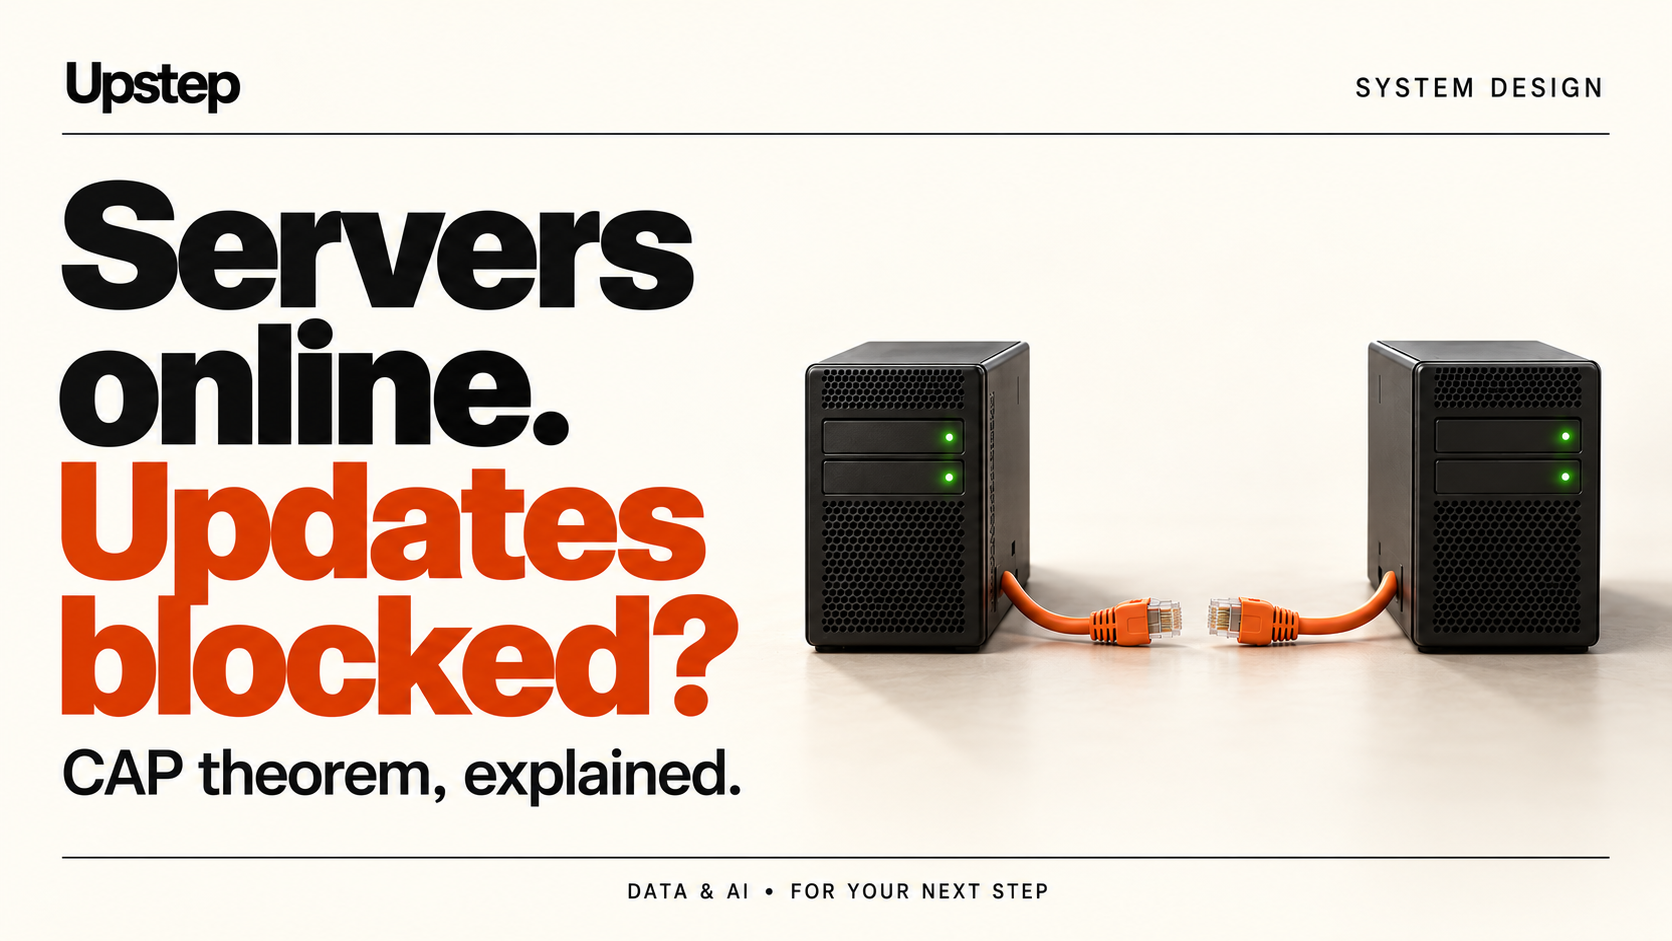
You have built an application with two servers.
Both store a copy of the same data. If one becomes unavailable, the other should keep serving users. It sounds like a sensible reliability improvement.
Then something unexpected happens.
Both servers are running. Both can receive requests. But the network connection between them stops working.
A user updates their delivery address through Server A. A moment later, another request asks Server B for that address.
What should Server B do?
Return the address it already knows? Wait until it can check with Server A? Refuse the request?
You now need to decide what your application promises when its parts cannot communicate.
This is the practical problem behind the CAP theorem.
What CAP actually means
A distributed system is a collection of computers working together. Because they communicate over a network, coordination can fail even when the individual computers remain healthy.
CAP describes a limitation involving three properties:
Property | Meaning |
|---|---|
Consistency | Operations behave as if they act on one copy of the data, respecting their real-time order. |
Availability | Every request received by a non-failing node eventually receives a response. |
Partition tolerance | The system must account for communication failures that prevent some nodes from exchanging messages. |
The consistency model here is called linearizability. For a simple read/write value, a read started after a completed write must reflect that write or a later one.
Availability has a specific theoretical meaning. CAP does not specify a response-time target. Returning “service unavailable” does not count as successfully serving the requested read or write.
During a network partition, a system cannot always guarantee both linearizability and availability. groups.csail.mit.edu
Follow one update through the system
Initially, both servers store:
delivery_address = "Address 1"
Now the connection between them breaks.
Server A receives an update to "Address 2" and confirms success to the user.
After that confirmation, Server B receives a read request.
Server B still holds "Address 1". It cannot determine whether Server A received an update.
Consider two policies.
Policy one: serve the local value.
Server B returns "Address 1".
The request completes, but the response violates the strong consistency guarantee: the earlier write had already completed.
Policy two: require coordination before answering.
Server B waits or reports that the operation is temporarily unavailable.
It avoids returning an unverified value, but it cannot guarantee that the read completes while communication remains broken.
The problem is missing information. A faster processor cannot tell Server B what happened on the other side of the partition.
Why “pick any two” is incomplete
The familiar CAP triangle helps people remember the letters. It is less useful as a design checklist.
In a networked application, choosing consistency and availability does not make communication failures disappear.
You must define what happens when communication fails.
Brewer’s later explanation emphasizes that choices can vary by operation and data. Recovery after a partition also belongs in the design. www.infoq.com
A more useful engineering question is:
“Which operations can safely continue with incomplete information?”
That connects infrastructure behavior to business consequences.
Start with the promise your feature makes
Consider a fictional online retailer.
Its product pages, wish lists, and order confirmation process do not necessarily need identical behavior during an incident.
Here is one possible design:
Operation | Proposed behavior during lost connectivity | Reason |
|---|---|---|
View a product description | Show a cached version | Temporarily outdated information may be acceptable. |
Add an item to a wish list | Record the change and reconcile later | The action does not promise stock. |
Display estimated stock | Show the last known value with a freshness notice | Browsing can continue without guaranteeing a reservation. |
Confirm a stock reservation | Require the authoritative reservation service | Confirmation creates a commitment that must be enforced. |
Notice the difference between showing information and making a commitment.
A page can remain useful while a particular action is unavailable.
My recommendation is to define those promises before assigning database labels. Start with the failure the business cannot accept, then identify the mechanism needed to prevent it.
Protecting consistency does not mean stopping everything
Which operations remain available depends on the coordination protocol and which nodes can still communicate.
Avoid assuming that a system must either accept every request or shut down completely. Gilbert and Lynch discuss designs that make different availability choices for reads, updates, and separate application components. groups.csail.mit.edu
For your architecture review, describe the consequences precisely:
Which requests stop?
Which requests continue?
What information can those responses contain?
Which users are affected?
“Unavailable” becomes much more useful when you explain it at the operation level.
Acknowledged, replicated, and visible are different states
Before building a demonstration, separate three events:
Event | What it tells you |
|---|---|
A server receives an update | The request reached that server. |
Another replica stores the update | Replication reached that replica. |
The client receives success | The system claims the operation completed under its defined rules. |
There is another decision: when may readers see the new value?
Suppose A exposes a new value before B receives it. The write remains unacknowledged because replication failed.
One reader sees the new value on A. A later reader sees the old value on B.
The lack of a successful write acknowledgment does not automatically make this sequence safe. Readers have already observed conflicting progress.
For a learning project, define visibility rules explicitly. Do not assume that “wait for two acknowledgments” is a complete consistency protocol.
Continuing through an outage creates recovery work
Imagine allowing independent wish-list updates on both sides of a partition.
When communication returns, the servers may contain different changes.
You need a reconciliation rule.
Combining additions using unique item identifiers might work for a simple example. But what happens when one device removes an item while another adds it?
Choosing the update with the latest timestamp is easy to explain, but it may discard an action the user expected to keep.
For your proposed design, write down how you will:
Identify changes and repeated requests.
Resolve conflicting operations.
Preserve the feature’s business rules.
Explain unresolved conflicts to users.
“Synchronize later” names work that remains to be designed.
Where CAP helps—and where it does not
CAP helps frame questions about shared data and communication failures. It is not a complete database-selection framework.
It does not determine which database is cheapest, whether your queries are efficient, or whether your schema represents the business correctly.
Likewise, a stale dashboard does not automatically demonstrate a CAP trade-off. A scheduled refresh may explain the delay without any partition.
Kleppmann’s A Critique of the CAP Theorem is useful further reading on the difficulty of mapping CAP terminology to practical system requirements. That critique should not be interpreted as disproving the formal theorem. arxiv.org
For a junior engineer, the habit to develop is simple: describe the failure and required behavior precisely before applying a label.
Build a small project: break the connection yourself
Create a Python simulator with two independent stores, A and B. Each holds an address and a version number.
Add a switch that enables or disables message delivery.
This is a learning exercise, not a production replication implementation.
Experiment one: normal operation
Write a new address to A, replicate it to B, and read from both.
Record when each event occurs, including when the client receives confirmation.
Experiment two: local responses during a partition
Disable communication.
Update A and acknowledge the write locally. Then read from B.
Your log should show a completed update followed by a read of the older value.
Explain which guarantee this policy gives up.
Experiment three: block updates while preserving unchanged reads
Start with identical replicas and no in-flight writes.
For this deliberately simplified experiment, disable communication before submitting an update. Keep the proposed update separate from the values readers can see.
Require both stores to participate before the update can complete.
During this partition:
The write remains pending or is rejected.
Neither replica exposes the proposed value.
Reads continue returning the same previously committed value.
These assumptions make the unchanged reads safe in this experiment. They do not establish that arbitrary local reads are safe in every replication system.
Restore communication, finish the update using the simulator’s controlled sequence, and verify both stores before resuming the test.
Experiment four: observe a visibility mistake
Repeat the test, but deliberately expose the pending value on A.
Read from A, then B.
Compare this result with experiment three. Explain why withholding a success acknowledgment was insufficient once readers could observe the pending change.
Your deliverable should include event logs, expected outcomes, actual outcomes, and the limitations of the simulator.
What this demonstrates in an interview
This project gives you concrete examples of replication, acknowledgments, stale reads, visibility, and failure testing.
More importantly, it helps you connect technical behavior to a user-facing promise.
When discussing a partition, first clarify the operation.
Are you displaying a recommendation, saving a preference, or confirming a reservation?
Then explain what must remain true, which operations may stop, and how the system recovers.
That shows you can reason about a design beyond reciting the CAP definition.
Your next step
Choose one feature from a project you have built and answer four questions:
What does a successful response promise?
What happens if two copies cannot communicate?
Which operations can continue safely?
What must happen before normal operation resumes?
Which operation would you pause first in your application—and why? Share your reasoning with Upstep.
Sources and further reading
Seth Gilbert and Nancy Lynch: Perspectives on the CAP Theorem — definitions and theoretical context.
Eric Brewer: CAP Twelve Years Later—How the “Rules” Have Changed — practical interpretation and recovery.
Martin Kleppmann: A Critique of the CAP Theorem — optional advanced reading.
The retailer scenario and simulator are illustrative teaching examples.